All 288 listings: page 3
Trending first. Showing 121–180 of 288.
 ▶ example at source
ComfyUI-H3-Motion-Context-MultiRef
MiniMax H3 nodes and workflows for extending clips, one-shot music videos, video-to-video motion transfer and custom keyframes.
 ▶ example at source
Two-reference character shot, first take (Seedance 2.5)
A prompt that maps @image1 (full body) and @image2 (close-up) to one character for 30 seconds at 720p.
 ▶ example at source
Goohai-MiniMax-H3_Integration
ComfyUI nodes for MiniMax H3's audio-video conditioning and reference-driven generation.
 ▶ example at source
seedance2-skill
An agent skill focused only on writing strong Seedance 2.0 prompts.
 ▶ example at source
Kandinsky 6.0 Pro (5s, Diffusers)
Kandinsky Lab's 6.0 Pro text- and image-to-video model with audio generation, packaged for Diffusers under an MIT license. Lite and distilled 5-second variants are published alongside it. The repo is gated.
 ▶ YouTube demo
Calliope
A local story-to-video app. It turns an idea into a storyline and script, splits scenes into shots, generates each shot through your own ComfyUI, then stitches the clips into a film with ffmpeg.
 ▶ example at source
ai-shortVideo-pipeline
Backend plumbing for an AI short-video service: multi-model failover, metering and quality gating.
 ▶ demo on X
Creature breaks out of a cinema screen, one take (Seedance 2.5)
A strict single-take prompt that forbids any cut: a creature appears to break out of a theatre screen, filmed on a phone.
 ▶ example at source
agnes-video-generator
A self-hosted web app that turns text into multi-scene videos with narration, subtitles and a presenter, powered by Agnes AI.
 ▶ demo at source
awesome-seedance
A large community collection of Seedance 2.0 prompts and resources across film, anime, UGC and ad styles.
 ▶ example at source
Mix-Studio
A polished front-end that runs tuned ComfyUI image and video workflows from desktop or phone without touching the node graph.
 ▶ demo on X
Pack goat rescue, one handheld take (Seedance 2.5)
A 20-second vertical, single-take, phone-camera prompt that tells a small rescue story (a goat leads a hiker to a trapped man) in documentary style.
 ▶ example at source
awesome-seedance-2-prompts
A curated library of Seedance 2.0 prompts by style, plus notes on API use and keeping characters consistent.
 ▶ demo at source
HunyuanVideo-1.5
HunyuanVideo 1.5, Tencent's lighter open video model aimed at running on more accessible hardware.
 ▶ example at source
higgsfield-seedance2-jineng
Fifteen Claude prompt skills for Seedance 2.0 on Higgsfield, each built around a hook-first structure for genres like CGI, anime and ads.
 ▶ example at source
wind-comic
A multi-agent pipeline that turns a one-line idea into a short drama: script, storyboards and character-consistent video, with swappable providers.
 ▶ example at source
SCAIL-2 (controlled character animation)
An open model from Zhipu (zai-org) that animates a reference character from a driving video end to end, without pose skeletons or masks. It also supports character replacement, multiple characters and animal driving.
 ▶ example at source
lanshu-awesome-ai-video-kit
A Chinese-language kit from enterprise video projects: hundreds of prompts across 15 models, Claude skills and methodology notes.
 ▶ example at source
ai-shortfilm-prompts
A Claude Code skill that turns a rough idea into a structured, model-ready video prompt, with 21 genre templates.
 ▶ example at source
Nomi
An open-source video workbench that lets coding agents direct any model or local ComfyUI over MCP, from storyboard to an editable first cut.
 ▶ demo on X
Luxury perfume bottle product shot (Seedance 2.0)
A compact product-ad prompt for a perfume bottle on glossy black with amber light and golden smoke.
 ▶ example at source
visual-skills
Agent skills that pair film-craft ideas (blocking, montage) with exact prompt syntax for Seedance, Kling, Veo and others.
 ▶ example at source
MiniMax-H3 Seamless Chain (multi-shot ComfyUI pack)
A ComfyUI node pack and two workflows that chain MiniMax-H3's roughly 10–15 second blocks into one continuous take, with no visible cuts, no colour shift between shots and a single continuous audio track. v2.7.0 adds per-subject voices.
 ▶ example at source
LTX-2.3 / LTX-2.5 ComfyUI workflows (RuneXX)
A collection of ComfyUI workflows for LTX-2.3 that the author says also work with LTX-2.5 models (with dedicated 2.5 workflows to follow). They are built around split model files that load more easily on smaller machines.
 ▶ example at source
flowboard
A local infinite-canvas tool where you wire model, product and scene nodes into product videos.
 ▶ example at source
higgsfield-ai-prompt-skill
A Claude skill bundle (32 sub-skills) for writing cinematic Higgsfield prompts, centred on Seedance 2.x features like omni-reference and extend.
 ▶ example at source
comfy-skills
Comfy's official plugin for coding agents. It adds slash commands and an MCP connection so an agent can generate images, video, audio and 3D, or run ComfyUI workflows on Comfy Cloud.
 ▶ example at source
comfyui-mcp
An MCP server plus sidebar agent that lets an AI assistant build, run and edit ComfyUI graphs in plain language, for images, video and audio.
 ▶ example at source
awesome-ad-video-prompts
A curated set of original, high-craft prompts for product and ad videos, written for Seedance 2.0, Veo 3, Kling and Runway.
 ▶ example at source
ai-media-generator
A Claude Code skill that drafts director-style prompts for image, video and music and can run them in a browser.
 ▶ example at source
vibe-creating-skill
A portable, bilingual agent skill that rewrites ideas into model-ready text-to-video prompts.
 ▶ example at source
DirectorSKILL
A Claude Code skill for shot lists and keyframe/video prompts, with ten selectable director-style overlays.
 ▶ example at source
velorn
An AI-native video editor organised around a real timeline, with generative steps and local agent control.
 ▶ example at source
ComfyUI-Easy-Media
ComfyUI nodes that simplify loading media and assembling video pipelines, with friendlier parameters than the defaults.
 ▶ demo on X
LTX-Video
Lightricks' official LTX-Video repo: open weights and inference code for one of the fastest open video models.
 ▶ demo at source
ComfyUI-WanVideoWrapper
Kijai's widely used ComfyUI wrapper for Wan video models. New Wan features and optimisations often land here before native nodes.
 ▶ example at source
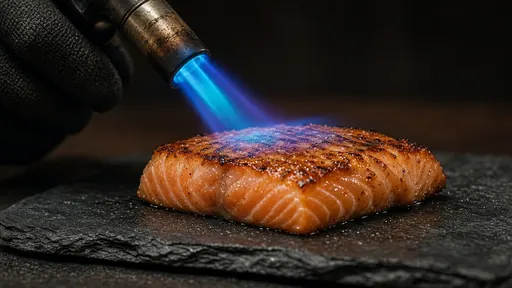
Blowtorch on salmon macro physics test (Veo 3.1)
A locked-off macro prompt that tests whether a blowtorch flame hits and spreads across food realistically, with lighting and film stock spelled out.
 ▶ example at source
ComfyUI-Bernini
A standalone ComfyUI plugin for the Wan 2.2 Bernini model, for generating and editing video.
 ▶ example at source
daVinci-MagiHuman (GAIR & Sand.ai)
A 15B single-stream transformer that generates human-centric video and speech audio together in six languages. The authors report a 5-second 1080p clip in 38 seconds on one H100, and pairwise human-eval wins over Ovi 1.1 and LTX 2.3. The base, distilled and super-resolution models are all released.
 ▶ example at source
awesome-ltx2
A maintained index of LTX-2 models, text encoders, LoRAs and ComfyUI workflows in one place.
 ▶ example at source
Vibe-Workflow
An open-source, node-based builder for chaining image and video generation steps, pitched as a free alternative to Weavy and Krea Nodes.
 ▶ example at source
LightX2V
A lightweight inference framework for text-to-video, image-to-video and image generation that supports several open models. There's also a hosted demo studio.
 ▶ YouTube demo
comfyui-deno-custom-nodes
A grab-bag of ComfyUI nodes: RTX Video Super Resolution, LTX 2.3 helpers, Wan 2.2 reference editing, and video compare and preview.
 ▶ example at source
ComfyUI-LTXVideo
Lightricks' official ComfyUI support for LTX-Video, the reference way to run LTX models in a graph.
 ▶ demo at source
goku
Code for the Goku video generation foundation models, a CVPR 2025 highlight paper.
 ▶ example at source
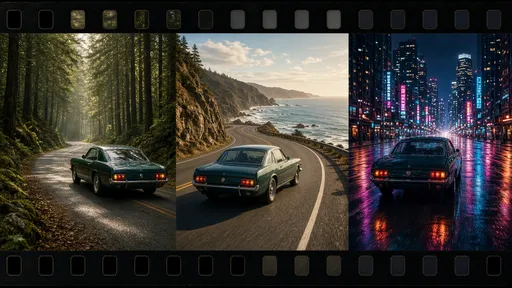
FastVideo
An open framework for faster video generation, covering both post-training and real-time inference. Docs and a cookbook are linked from the repo.
 ▶ example at source
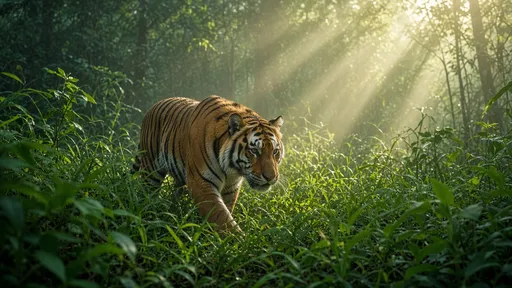
LongCat-Video (Meituan)
A 13.6B open video model that handles text-to-video, image-to-video and video continuation in one network. It is pretrained on continuation, so it can produce minutes-long videos without colour drift, and it renders 720p at 30 fps using a coarse-to-fine strategy and block-sparse attention.
 ▶ demo at source
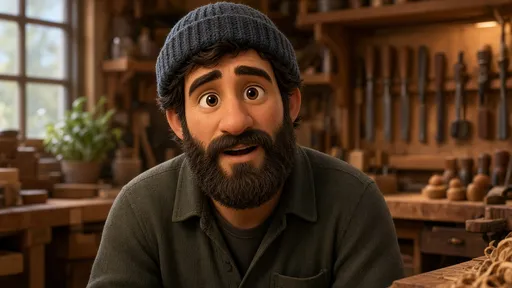
ComfyUI-HunyuanVideoWrapper
Kijai's ComfyUI wrapper for Tencent's HunyuanVideo, an early way to run it locally with memory optimisations.
 ▶ demo at source
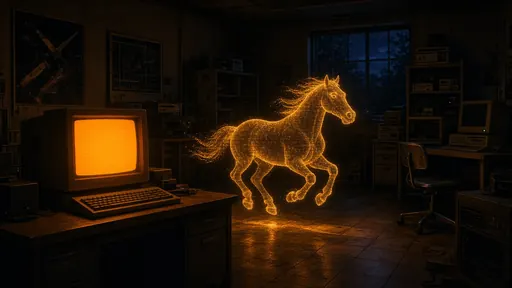
ID-LoRA-LTX2.3-ComfyUI
A ComfyUI node for LTX 2.3 that makes video carrying one person's identity, from a reference image and voice. Use only with consent of the person shown.
 ▶ example at source
egaki
A command-line tool for generating images and video from the terminal across Google, OpenAI, fal, Replicate and Seedance. Agents can use it too.
 ▶ example at source
comfyui-vrgamedevgirl
A large ComfyUI node pack for AI video production. Its main tool, the AI Video Builder, plans, prompts, generates, reviews and assembles a video scene by scene, with LTX 2.3 and MiniMax H3 support.
 ▶ example at source
ComfyUI-PainterNodes
A ComfyUI toolkit spanning video generation, image editing and audio-driven lip-sync across Flux, MiniMax, LTX and Wan 2.2.
 ▶ demo at source
seedance-2-generator
A starter SaaS codebase (Next.js, Stripe, NextAuth, Prisma) for selling Seedance 2.x video generation.
 ▶ example at source
Lance – image/video generation and understanding in one model
Lance, from ByteDance, is a single model for both generating and understanding images and video, with code, paper and weights linked.
 ▶ demo on X
Rainy-night urban thriller walk (Seedance 2.5)
A 30-second suspense prompt that follows a woman from a subway exit through rain-soaked streets, beat by beat.
 ▶ example at source
vibeframe
A CLI and MCP server that lets a coding agent turn a brief into a finished MP4 using your own Seedance, Runway, Kling or Gemini keys. Every paid step has a dry-run price and a hard spending cap.
 ▶ demo at source
awesome-video-prompts
A prompt collection for Veo 3/3.1, Kling and Hailuo, organised by scene type.
 ▶ YouTube demo
A Pipeline for Making 10-minute AI Movies with Claude Code and Seedance
A Claude Code pipeline that makes 10-minute films with Claude as director, combining Seedance for video, Nano Banana for images and ElevenLabs for voice.
 ▶ example at source
Text-to-video model from scratch (2 brothers, 2 years, 2B params)
Two brothers trained a 2B-parameter text-to-video model from scratch. Their write-up shows both good and bad samples.
 ▶ example at source
Krea Realtime 14B
Krea's realtime model, distilled from Wan 2.1 14B with Self-Forcing into an autoregressive generator. You can change prompts mid-generation, restyle on the fly and see first frames within about a second. It also streams video, webcam or canvas input for video-to-video.